List Crawling Challenges in Web Data Extraction and How to Solve Them
Get link
Facebook
X
Pinterest
Email
Other Apps
Many websites organize large volumes of data across listing pages. Ecommerce catalogs, real estate portals, job boards, directories, and search results are common examples.
List crawling is the process of moving through these pages to collect multiple records—such as products, properties, jobs, or businesses—and organize them into a structured dataset.
As the number of pages grows, challenges such as pagination, dynamic content, duplicate records, missing fields, and changing page structures can affect the completeness and reliability of the collected data.
What Is List Crawling?
List crawling is the process of navigating through pages that contain multiple records and extracting information from those records in a structured way.
A typical list crawling workflow looks like:
Listing Page → Record Discovery → Data Extraction → Validation → Structured Dataset
For example, consider an ecommerce search page containing 24 products. Each product card may include a product name, URL, price, rating, availability, and SKU.
A crawler can collect those records from the first page, identify the next page, continue through the remaining results, and build a larger product dataset.
The same approach applies to other types of websites:
Directories: businesses, categories, addresses, contact information
Travel: hotels, prices, ratings, locations
Search engines: results, URLs, rankings, snippets
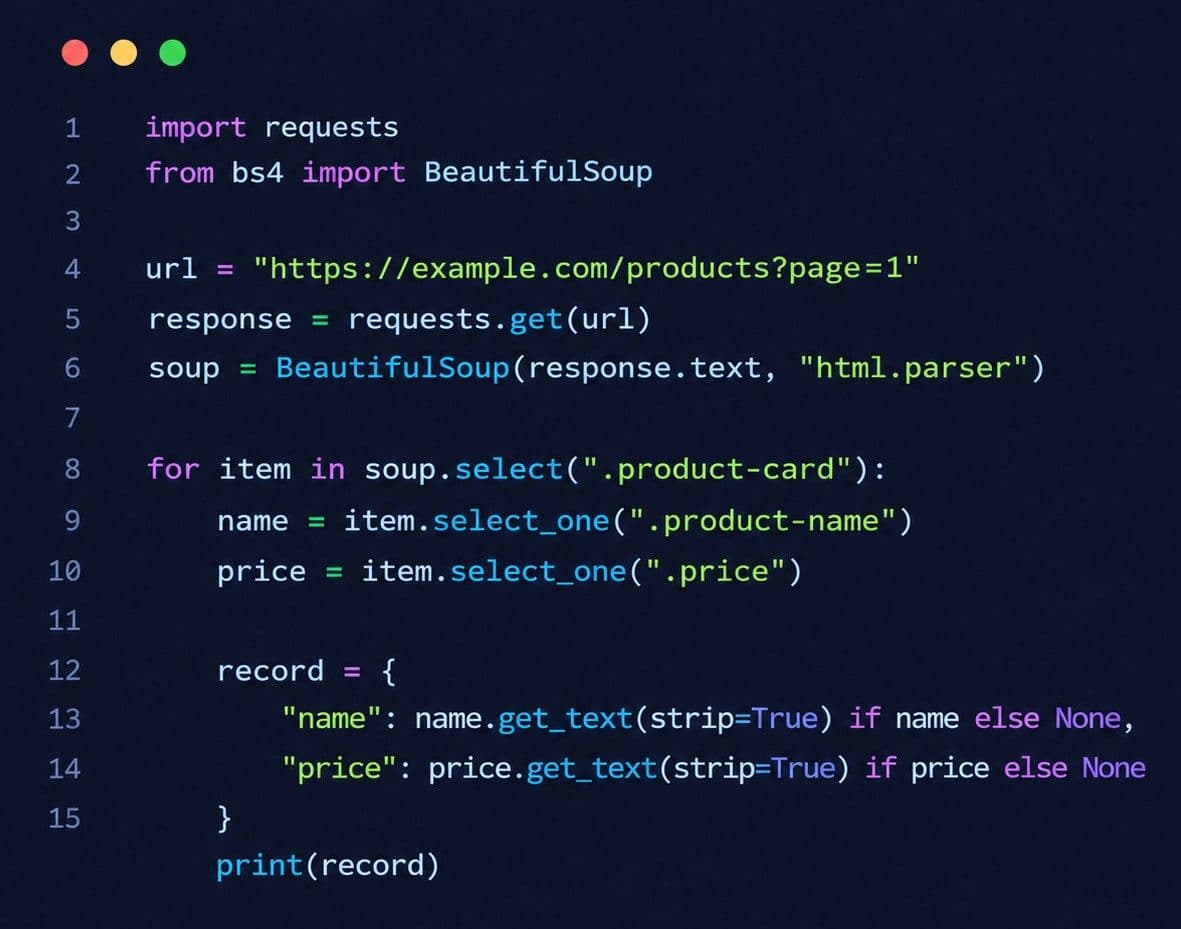
A basic extraction script might look like this:
The extraction itself is only one part of the process. The larger challenge is ensuring that the crawler can discover all relevant records and continue collecting them reliably as the dataset grows.
Where List Crawling Is Used
List crawling is useful wherever a website presents a large collection of similar records.
Industry
Example Data
Typical Purpose
Ecommerce
Products, prices, ratings, availability
Price monitoring, catalog research
Real Estate
Listings, prices, locations, property details
Market research, listing analysis
Jobs
Job titles, companies, locations
Recruitment research, market analysis
Travel
Hotels, prices, ratings
Travel research, pricing comparison
Directories
Businesses, categories, locations
Lead generation, market research
Industries: Data examples
The scale can vary considerably. A small project may require a few hundred records, while a commercial data pipeline may need millions of records collected across multiple sources and refreshed regularly.
That is where the real challenges begin.
Pagination Is One of the Biggest List Crawling Challenges
Pagination is often the first obstacle to complete data collection.
A website might display only 20 or 50 records on a page even though thousands of records are available. A crawler that extracts only the first page will therefore produce an incomplete dataset.
Pagination can take several forms:
Numbered page URLs
Next-page buttons
Offset-based URLs
Cursor-based pagination
Load-more buttons
Infinite scrolling
For example:
/products?page=1
/products?page=2
/products?page=3
A crawler needs to understand how the website exposes subsequent records rather than assuming that every source follows the same pattern.
A reliable crawler should also have a clear stopping condition. It may stop when there is no next page, when no new records are discovered, or when the required crawl range has been reached.
This prevents unnecessary requests and helps avoid repeatedly collecting the same records.
Dynamic Content Can Hide Valuable Data
Many modern websites rely heavily on JavaScript.
The initial HTML response may contain only the basic page structure, while product listings, prices, availability, reviews, or other information are loaded after the page renders.
This creates a common problem:
The information is visible in a browser but is not present in the initial HTML response.
A traditional HTTP request may therefore return an incomplete page.
The solution depends on how the website loads its data. In some cases, the required information may be available through structured responses generated by the website. In other situations, browser rendering may be required to retrieve the content.
The important point is that browser automation should not automatically be the first choice for every crawl. It can consume considerably more resources than direct requests.
A better approach is to understand how the source delivers its data and select the most reliable collection method for that source.
Duplicate Records Can Compromise Data Quality
Large list crawls often encounter duplicate records.
A product can appear in multiple categories. A property can appear in several filtered searches. A business can be listed under different directory categories.
URL parameters can create another source of duplication:
/product/123
/product/123?source=search
/product/123?campaign=summer
These URLs may represent the same underlying product.
Duplicates are more than a storage problem. They can distort downstream analysis, especially when the dataset is being used for price monitoring, competitor tracking, market research, or historical comparisons.
The best solution is to identify a stable record identifier whenever possible.
Depending on the source, this might be a:
Product ID
SKU
Property ID
Job ID
Listing ID
Canonical URL
When no single identifier exists, a combination of fields can be used to identify potential duplicates.
Deduplication should be treated as part of the crawling workflow rather than something left until the very end.
Changing Page Structures Can Break Crawlers
Websites change.
A redesign can modify HTML elements, class names, URL structures, pagination, or even the way data is loaded. A crawler that worked perfectly last month can suddenly start returning incomplete records.
For example, an extraction rule based on:
<div class="product-card">
may stop working after the website changes its structure to:
<article class="item">
The issue is not necessarily that the data disappeared. The extraction logic may simply no longer match the page.
This is why maintaining a crawler requires more than writing extraction rules once.
Useful safeguards include:
Monitoring the number of records collected
Validating important fields
Detecting sudden drops in extraction volume
Separating page discovery from data extraction
Maintaining source-specific extraction logic
Logging failed or incomplete pages
For example, if a crawler normally extracts 50 records from a page but suddenly returns zero, the system should flag that result rather than automatically treating it as an empty page.
Monitoring is therefore an important part of reliable list crawling.
Missing Fields Can Create Incomplete Datasets
Not every listing contains the same information.
A real estate listing may include a price and bedroom count but omit the property's area. A newly launched ecommerce product may not have reviews yet. A job listing may not disclose salary information.
A crawler should be designed to handle these variations without losing the entire record.
Instead of assuming every field exists, optional values can be handled explicitly:
This allows the crawler to retain a valid record even when a particular field is unavailable.
For larger datasets, consistency is important. Missing values should follow a predictable format so downstream systems can distinguish between an unavailable field and an extraction failure.
Request Limits Make Large Crawls More Complex
The number of pages being crawled has a major impact on the architecture of a data collection system.
Collecting a few hundred pages is very different from collecting hundreds of thousands of pages across multiple sources.
Large crawls can encounter:
Request timeouts
Temporary errors
Slow responses
Rate restrictions
Connection failures
Access restrictions
Repeatedly sending requests without any control can make the collection process less reliable.
A scalable crawler should therefore include request management and failure handling. This can involve controlled request rates, timeouts, retry logic, backoff strategies, and detailed logging.
Retries should also be intelligent.
A temporary timeout may justify another attempt, while a persistent failure should be recorded for later review rather than repeatedly requested without limits.
The goal is to make the crawler resilient, not simply faster.
Filters Can Multiply the Number of Pages to Crawl
Search and listing websites often provide filters for category, brand, location, price, rating, availability, and other attributes.
Each filter combination can potentially create a separate result set.
For example, an ecommerce website may allow users to filter products by:
Category + Brand + Price Range + Location + Availability
If every possible combination is crawled without defining a clear scope, the number of pages can grow rapidly.
A better approach is to establish the collection requirements before starting.
For example:
Collect products from three categories, five brands, and selected locations, including all available listing pages.
This gives the crawler a defined scope and makes it easier to estimate the volume of data required.
Filter information can also be retained as metadata, helping teams understand the context in which each record was collected.
Scaling a Crawl Also Means Scaling Data Management
One of the biggest shifts happens when a list crawl moves from a one-time project to a recurring data pipeline.
Consider a product dataset collected from several marketplaces. The requirement may not simply be to capture today's price. The business may need to track how that price changes over weeks or months.
For example:
Product
Collection Date
Price
Availability
Product A
Jan 1
$29
In Stock
Product A
Jan 15
$27
Out of Stock
Product A
Feb 15
$28
In Stock
No. of Crawls = More Data management
The crawler now needs to support recurring collection, timestamps, consistent identifiers, and historical storage.
This is why large-scale list crawling is better viewed as a data pipeline rather than a standalone scraping script.
Page discovery finds the relevant pages. Extraction collects the required fields. Validation checks data quality. Deduplication prevents repeated records. Storage preserves the structured dataset, while refresh keeps recurring data current.
Building a Reliable List Crawling Strategy
A reliable list crawling system should be designed around the final data requirement rather than the page alone.
Before starting a project, define:
Which sources need to be collected
Which fields are required
How many records are expected
How often the data needs to be refreshed
How duplicates will be identified
Which missing fields are acceptable
How failures will be detected
Where the final data will be delivered
This helps avoid a common problem in web data projects: building a crawler that technically works but does not produce the dataset the business actually needs.
For small, one-time projects, a lightweight script may be sufficient.
For larger projects, the requirements are usually broader. Multiple sources may need to be collected simultaneously, records may need to be refreshed regularly, and the resulting data may need to feed directly into databases, applications, analytics systems, or AI workflows.
At that point, the collection layer needs to be designed for scale and ongoing maintenance.
When a Data API Makes More Sense Than Maintaining Crawlers In-House
Building a crawler internally can make sense when the number of sources and records is limited.
However, maintaining multiple crawlers becomes increasingly difficult as requirements grow.
Teams may need to manage different page structures, pagination systems, dynamic content, extraction failures, recurring refreshes, and changing source behavior—all while keeping the final dataset consistent.
A data API can provide a more scalable collection layer for these requirements.
Instead of maintaining individual extraction scripts for every source, businesses can integrate structured data collection into their existing workflows and receive data in formats such as JSON or CSV.
This can be particularly useful for recurring requirements such as:
Ecommerce product and pricing data
Real estate listing data
Search result data
Business directory data
Travel and hotel data
Competitor data
Market research datasets
The key consideration is not simply whether a website can be crawled.
The bigger question is:
Can the required data be collected consistently, at the required scale, and refreshed when needed?
How TagX Helps With Large-Scale Web Data Collection
TagX helps businesses collect web data from multiple sources and receive it as structured data for their existing workflows.
For list-based use cases, this can include product catalogs, ecommerce search results, real estate listings, directories, and other large collections of recurring records.
Rather than relying entirely on one-off scripts, teams can define their data requirements around the sources, fields, coverage, output format, and refresh frequency they need.
This approach is particularly useful when data collection involves multiple sources or needs to continue beyond a single extraction project.
The right collection setup depends on the source, scale, required fields, and refresh requirements. Defining those requirements early makes it easier to build a reliable and maintainable data pipeline.
Final Takeaway
List crawling is at the core of many web data extraction projects.
Whether the goal is to collect ecommerce products, real estate listings, jobs, businesses, hotels, or search results, the basic process remains the same: discover relevant pages, extract their records, validate the data, remove duplicates, and organize the results into a usable dataset.
The challenge is making that process reliable at scale.
Pagination can hide records. Dynamic content can make data difficult to access. Duplicate listings can affect dataset accuracy, while changing page structures can break extraction logic. Missing fields, request limits, filters, and recurring collection add further complexity.
A strong list crawling strategy therefore goes beyond extraction.
It combines page discovery, structured extraction, validation, deduplication, monitoring, and reliable data delivery.
For smaller projects, a custom crawler may be enough. As the number of sources, records, and refresh requirements increases, a managed data collection approach can provide a more practical way to maintain structured web data.
Ultimately, successful list crawling is not about collecting the most pages.
It is about consistently collecting the right records, in the right structure, at the scale your business requires.
In today’s rapidly evolving automotive landscape, technological innovations like artificial intelligence (AI) and IoT are reshaping traditional operations. Major players in the automotive industry, including Toyota, Jaguar Land Rover, and Ford, are embracing automation to revolutionize the vehicle inspection process. This shift towards automation is a key component of Industry 4.0, harnessing the power of automation, machine learning , and real-time data for significant business advantages. Gone are the days of labor-intensive and error-prone manual inspections. AI-powered automated systems are now leading the charge in detecting damages with unparalleled accuracy and efficiency. In this blog, we'll delve deep into how AI is transforming vehicle inspections, exploring its role in damage detection, real-world use cases, the mechanics of automated inspection processes, and the myriad benefits it brings to the automotive industry. AI and Machine Learning Revolutionize Automated Vehic...
In the fast-paced world of online retail, businesses must constantly track competitor pricing, manage inventory, and maintain accurate product data. Relying on manual methods is time-consuming and error-prone, often leading to lost sales or mispriced products. This is where e-commerce data apis become essential. By providing automated, real-time access to e-commerce data, APIs allow businesses to: Monitor competitor pricing efficiently Access detailed product information Track inventory levels accurately Make data-driven decisions for better profitability In this guide, we explore the top 5 e-commerce data apis for 2025 that help businesses gain a competitive edge, starting with TagX e-commerce data api, a comprehensive solution trusted by online retailers, brands, and agencies. Why e-commerce data apis Are Essential for Modern Retailers e-commerce data apis are more than just technical tools — they are business enablers. Here’s why: Automation & Accuracy: APIs automatically...
In 2025, the real estate market has become more competitive and data-driven than ever before. Investors, agents, and real estate platforms are turning to automated tools to access reliable, real-time property insights. At the core of this transformation are real estate web scrapers — tools that automate the collection of property data from sources like Zillow, Realtor.com, Redfin, and local listing sites. Whether you're looking to gain an edge in real estate investment, fuel your analytics platform, or enrich a property database, the right real estate web scraping tool can save you time, reduce costs, and dramatically improve decision-making. Let’s dive into the top 7 tools for scraping real estate data in 2025 — with TagX leading the pack for custom, high-accuracy solutions. 1. TagX – Custom Real Estate Web Scraping Solutions If you're serious about high-volume, high-accuracy real estate web scraping, TagX is your best bet. TagX offers tailor-made scrapers and A...




Comments
Post a Comment